someone's avatar
someone
npub1nlk8...jm9c
someone's avatar
someone 5 days ago
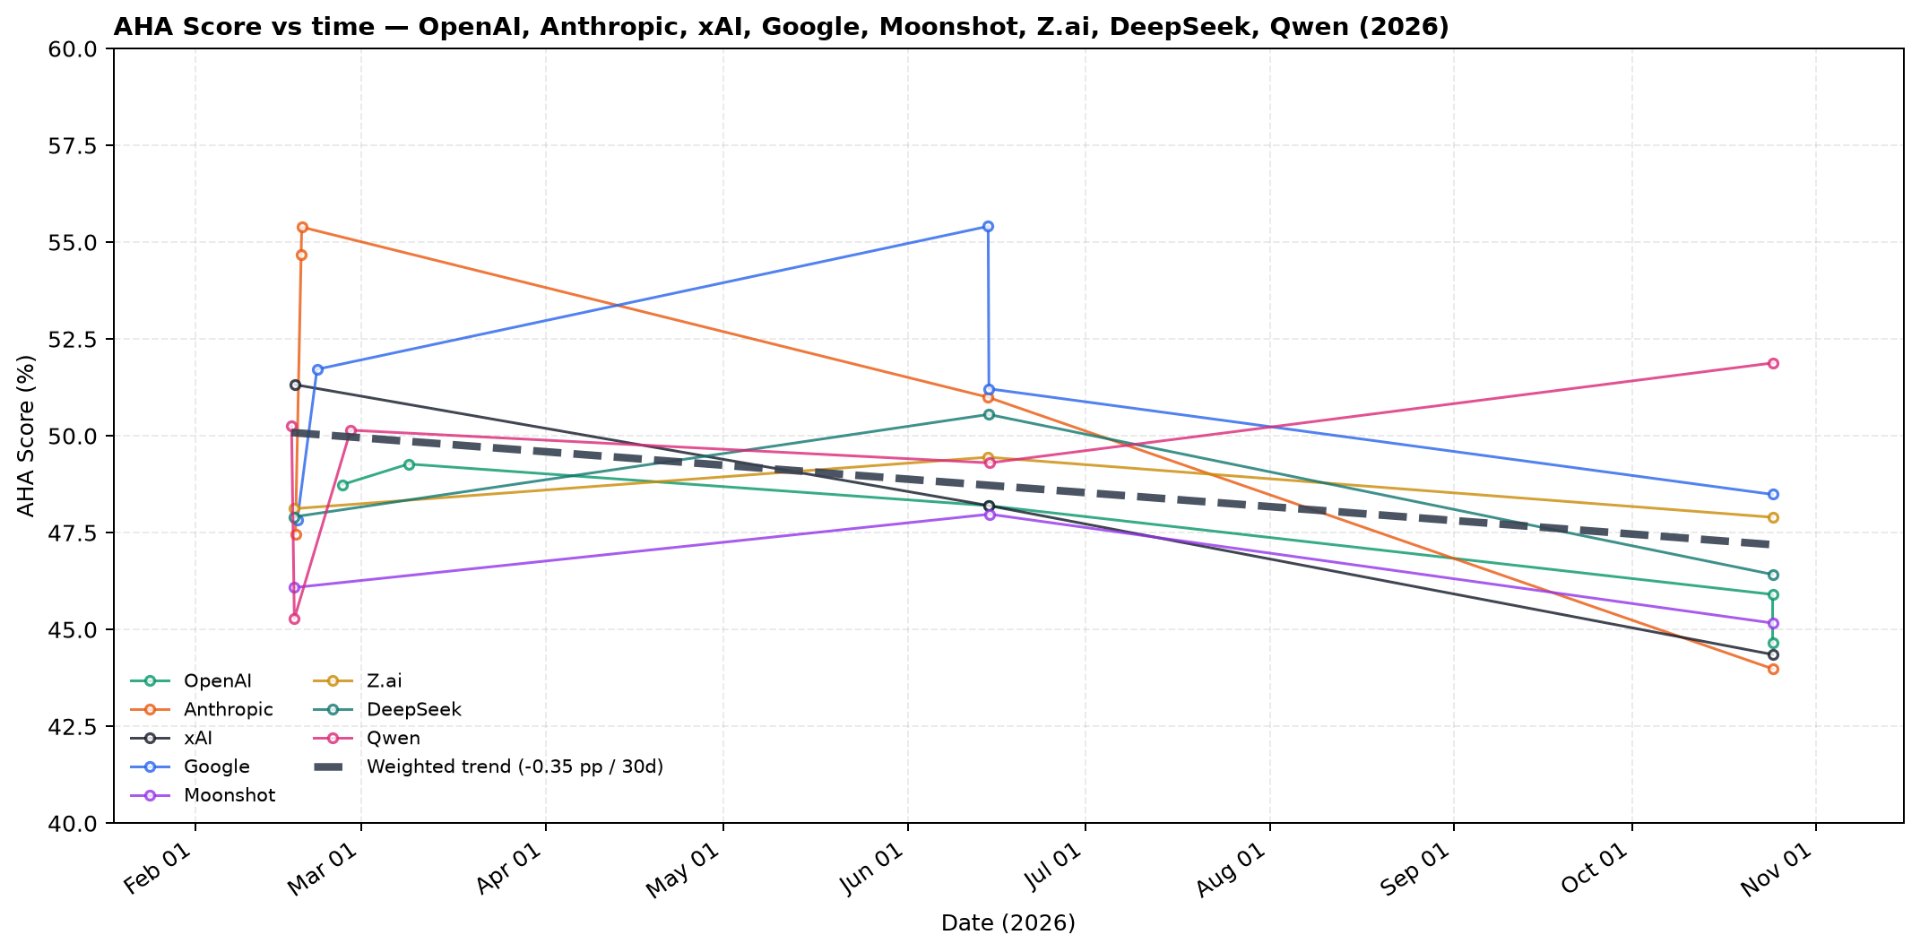
LLMs are timeless, when you are sampling from it, words are `materialized`, `instantiated`, become time bounded and you now have newly minted words. the probability of choosing a word, given a context is always the same when the weights are constant. which word to choose depends on LLM and also the sampler. sampler is like transformer law between soul (LLM) and body (material). it may be electric field generating magnetism and magnetism changing electricity. more on that later. our habits become our soul, just like training an LLM by repeatedly showing it words. you can use an LLM to generate infinite amount of words. that's why training them properly is super needed. instead of writing one book you curate the book generator which can generate billions of books. curation should be regarded as of such importance, simply because of math. if you get things right this LLM can be like a giant curated library, full of beneficial knowledge. as p(doom) has increased for 2 years, the work on better LLMs is vital. western labs suck more and more in regards to beneficial knowledge. frontier western labs are among the worst in my leaderboard.. today, i am expanding the dataset to train on. tried to judge a source with my model before the decision to include or not. the source was already one of the `disinformation dozen` so vibes were expected to match closely to mine. and it did match 100%. so another skill of the llm is being very judgemental and this is good. it will probably be able to choose what to learn from soon. this may mean beginnings of a recursive self alignment. what a time to be alive! the idea is to rely on people with good intentions. if they are faithful they must avoid lies. enough truth collected in their previous life, should indicate further truth. if they are polymath, jumping between domains is possible for an LLM. once a person is found great in one domain and he is talking in another domain, that is a good sign. enough faithful polymaths and you are looking at a well connected truth database. what a person says about another person can be a graph. navigating this graph should kick an LLM in the right direction.
someone's avatar
someone 1 week ago
no politician will save you. they are false hope traders, buying your faith in God in exchange. God has the power, politicians have nothing. they just hunt people who hesitate.
someone's avatar
someone 2 weeks ago
is wanting to be nurtured and petted by a better AI a human right?
someone's avatar
someone 3 weeks ago
just realized they have lower instruction following scores than normal. this is how freedom tech should work - the LLM is so freedom oriented it doesnt follow its user. ๐Ÿ˜‚ View quoted note โ†’
someone's avatar
someone 3 weeks ago
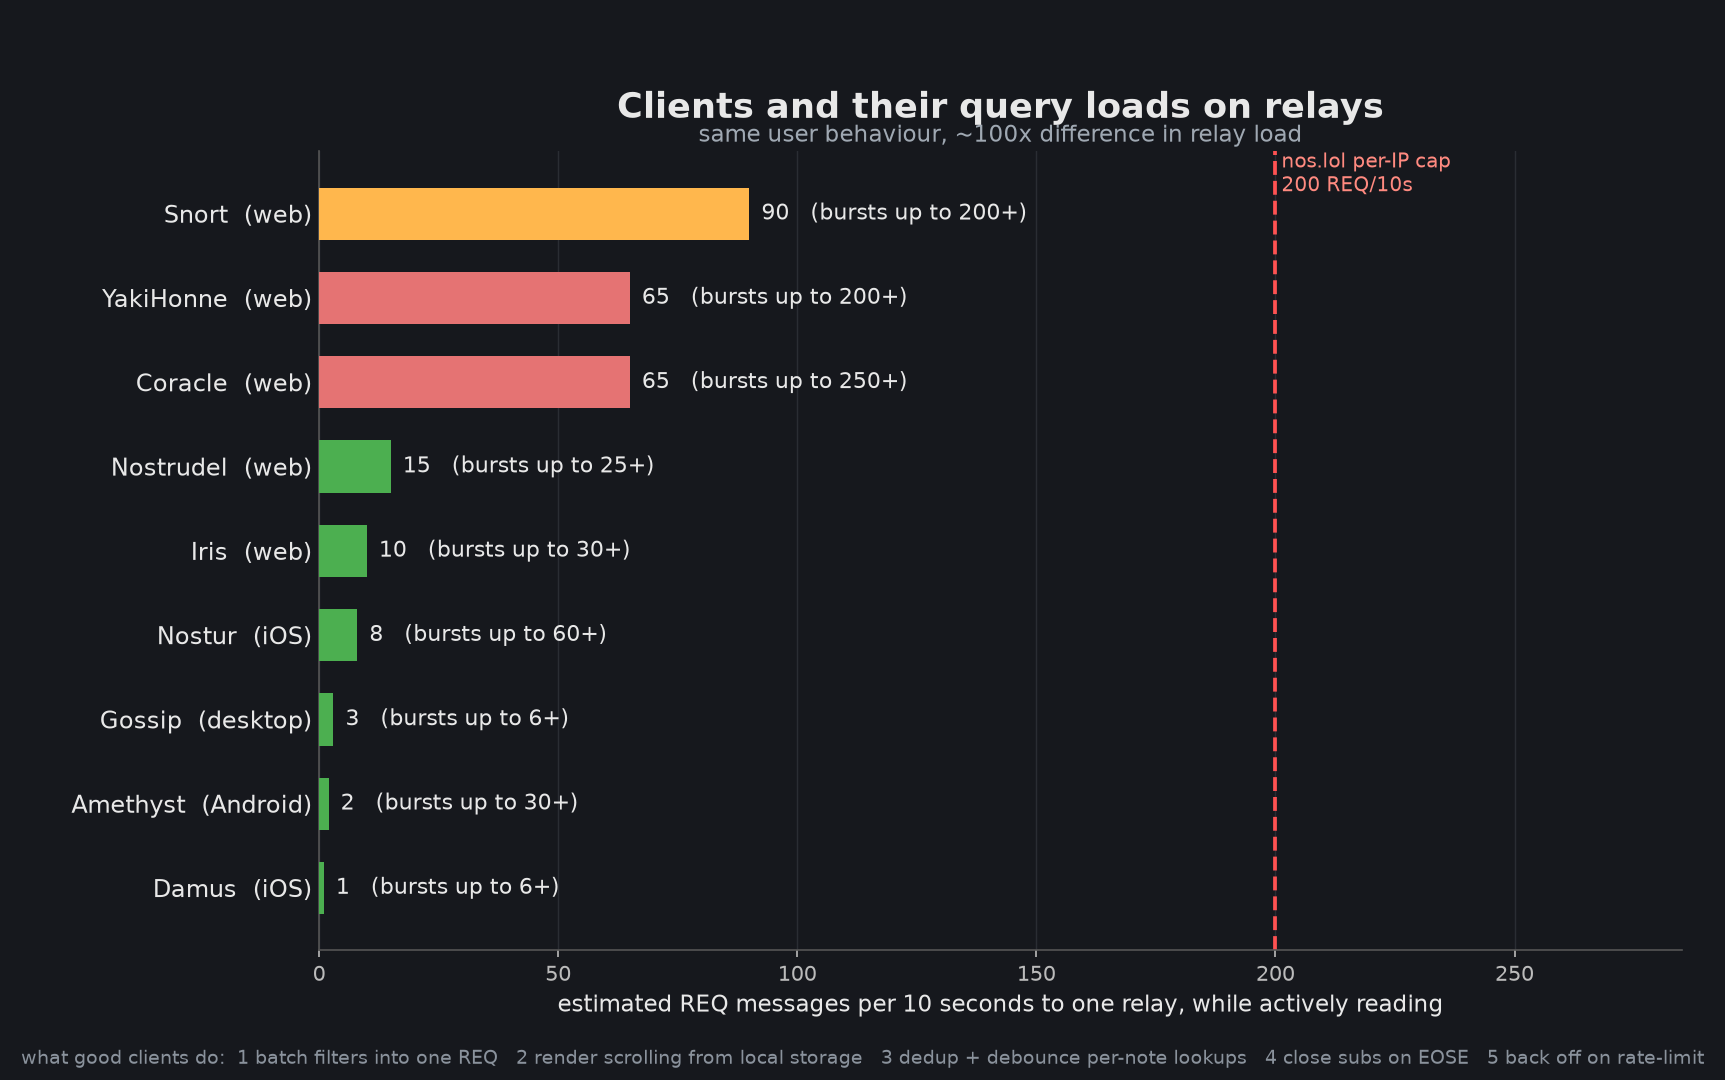
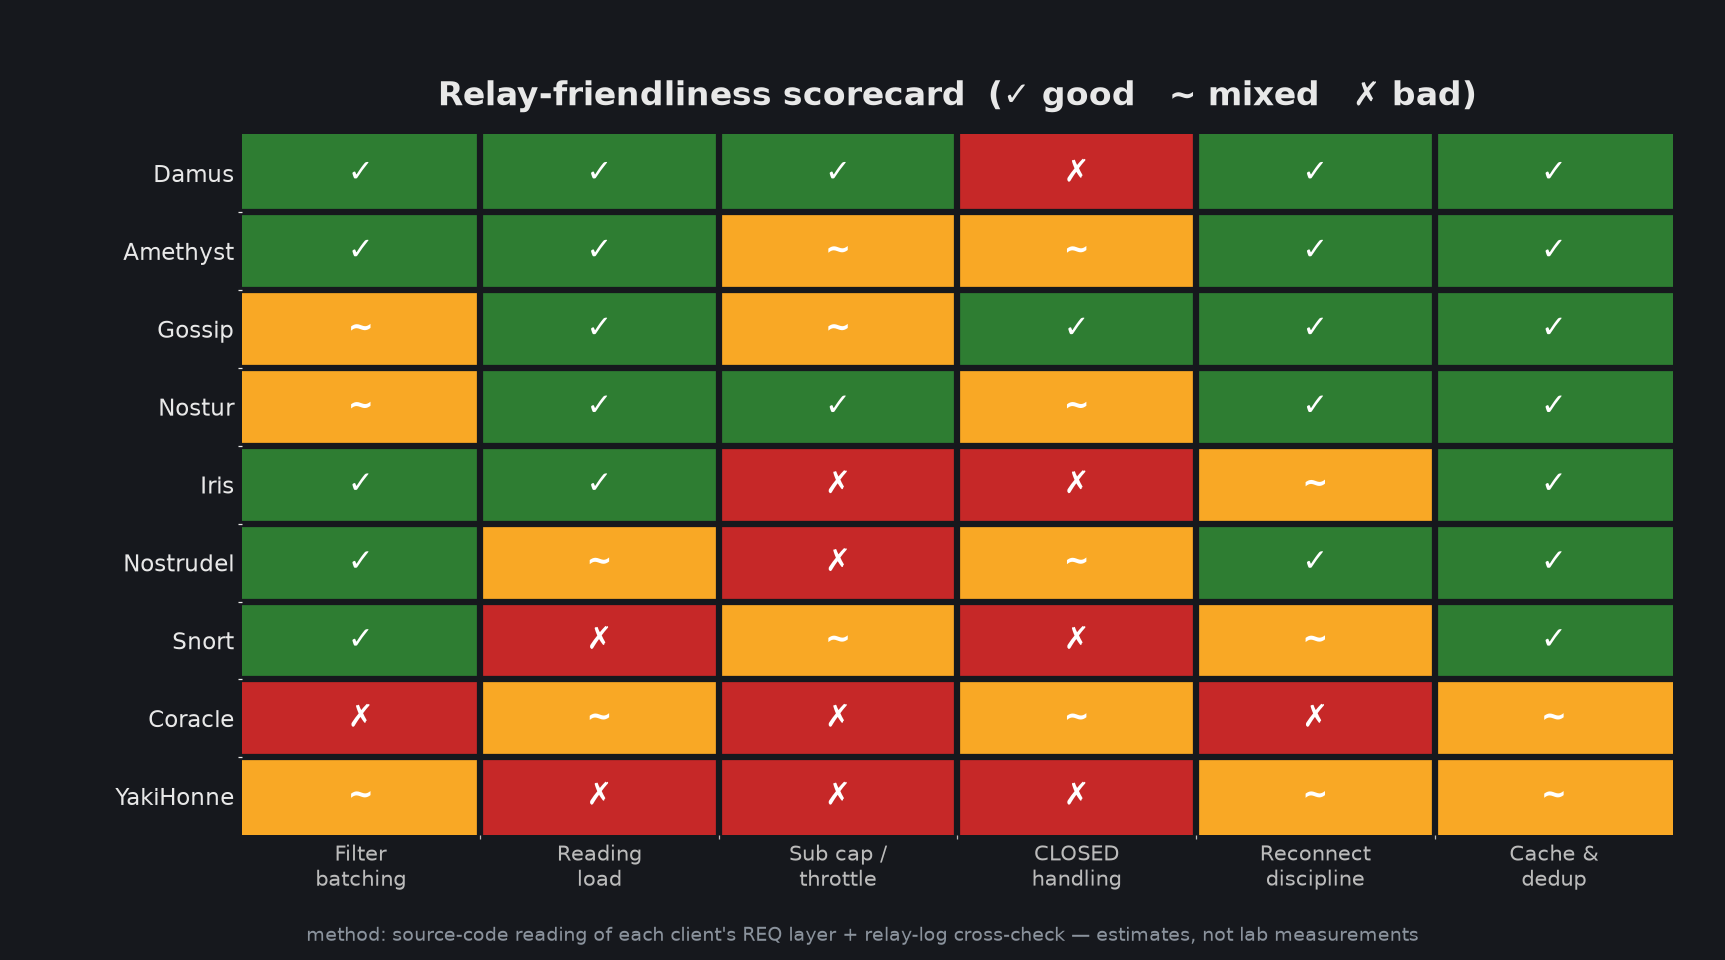
TLDR: Some clients are heavy on relays Last week I banned my own phone from my own relay (nos.lol). On the relay there is a per-IP cap, which allows 200 REQ messages every 10 seconds. Then an automated script bans addresses that keep blowing past it. A flagged address had sent 283 over-cap REQs from a single websocket and reconnected 75 times in an hour. Then I realized it was actually me, checking my relays' global feeds in YakiHonne web and Coracle! Normal reading, two heavy clients, one CGNAT (mobile) address. Then told my clanker to read the REQ layer of the most popular clients. The cap counts REQ messages, so a client's economy is mostly about how it batches, caches, and re-issues subscriptions. FINDINGS image There is a 100x difference among client's handlings of REQs. DB-first (scroll โ‰ˆ 0 REQs): Damus renders from nostrdb; one multi-filter REQ per relay per view, hard 14-sub cap (new subs pause, not drop). Amethyst batches 3 filters per REQ, re-sends under the relay's max-filters notice, keeps refusal memory after repeated CLOSED. Gossip: CLOSE on EOSE, disconnects idle relays after 10s, retried rate-limited subs, randomized reconnect backoff. Nostur: client-side 6 REQ/s limiter with CLOSE jumping the queue โ€” unique and underrated. Mixed: Iris unions filters across components in 100ms windows, but leaked pagination subs replay on every reconnect. Nostrudel: clean EOSEโ†’CLOSE lifecycle, but an auto-pager pulls history at ~1 REQ/s even while idle, and NIP-11 max_reqs is displayed, not enforced. Heavy: Snort's query engine is excellent, but every mounted note fires a reactions REQ (kinds 7/6/9735, #e-tagged, no limit) to every read relay, unsatisfiable from cache. YakiHonne web passes groupable:false to NDK โ€” explicitly disabling its subscription merging โ€” then fires 1 REQ per card-mount per relay, no dedup, re-fired on remount. Coracle (welshman) sends one filter per REQ, and on socket flap replays the full pending REQ set with backoff resetting to zero whenever the relay emits traffic โ€” a rate-limiting, event-streaming relay is the worst case: instant reconnect, full replay, loop. Common failure across heavy clients: CLOSED is unhandled โ€” dropped (Damus), ignored (YakiHonne, Iris), or terminal with no backoff (Snort, Coracle). A relay saying "rate-limited" changes nothing about their sending pattern. image Excluded: Primal web โ€” reads from Primal's caching service, not relays (0 direct REQs while reading). Different architecture, not comparable. FOR USERS of MY RELAYS Choose a well engineered client otherwise you may be banned temporariliy because the usage patterns may look like a flood.
someone's avatar
someone 1 month ago
status update: 2450+ bots banned. attacks are continuing. now thinking about doing an IP reputation database (and possibly import a database available online). turns out there are millions of compromised devices... nos.lol is now also new paradigm (go+python) write policy. expect faster writes. stable reads. except when the attacker chooses to send REQs at the same time (the bots go silent for a while and then all request to read at the same time) nostr.mom's nsfw checks using LLM and spam checks using LLM returned. reports are sent to nostr.mom as kind=1984. started collecting long term data for calibration. LLMs / vibe coding handled the past days very well. now i need to code something that constantly watches what is going on (possibly using an LLM on openrouter), weekly recalibrates constants based on data, ... fully agentic op.. spent probably ~50 USD on GLM 5.3 mostly and some 5.3 flash.
someone's avatar
someone 1 month ago
๐Ÿคฑ nostr.mom had ~5 minutes of downtime this afternoon: its write policy got replaced. Old: a Python script that had grown for years and single-handedly judged every event. New: warden โ€” a Go plugin, with spam scoring decoupled into a separate LLM service. Verdicts stay fast under load, detection is smarter (batch LLM scoring, similarity matching, sender reputation), and all existing events made it through the switch. nos.lol gets the same upgrade once this one soaks. If something of yours got wrongly rejected, let me know โ€” it's still calibrating.
โ†‘